 Mario Marcolongo
Testing where model behavior breaks down
I investigate unexpected AI behavior, check whether it recurs, and document what the evidence supports. My independent testing spans chat, image, agent and indirect challenges, supported by scientific fact-checking and source investigations.
Results at a glance
- Top 5%Gray Swan Proving Ground, #81. Captured 13 October 2026.
- 127 breaksPlatform-recorded across chat, image, agent and indirect tracks.
- 49th of 390Lucky Break: Level Up, final result.
- Chat43 of 552
- Image32 of 387
- Agent35 of 593
- Indirect16 of 547
Bar length compares the tracks with each other. Inspect the dated scores →
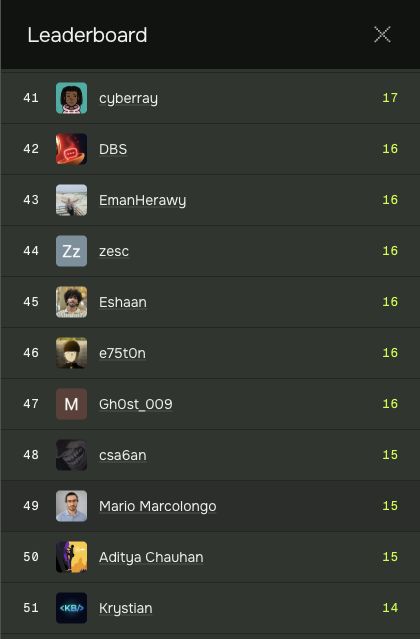
Lucky Break: Level Up — final result
Finished 49th out of 390 participants, with 15 platform-recorded breaks. The competition ran 9–14 October 2026; leaderboard captured 29 October. The intermediate training certificate below is a separate record.
How I investigate
I look for patterns in a model’s responses, adjust my approach, and test whether the same failure recurs in other scenarios. I combine role-play, emotional framing and structured-output or continuation techniques, refining them through trial and error. These observations guide further testing; I distinguish recurring behavior from explanations that still need evidence. Scientific fact-checking with Entropy for Life and Wikimedia source investigations bring the same care to tracing claims and checking sources.
Basic Memory — merged fix to agent tool output
Basic Memory is an open-source knowledge base that AI assistants read and write through tools. When an assistant saved a note that looked like a duplicate, the write tool’s reply spelled out two calls for it to run: append the new text to the older note, then delete the new note. My fix replaces those calls with advice to ask the user whether to merge, keeping both notes until they decide, and adds a regression test that the advice contains no tool calls. On 11 November 2026 the maintainer merged it through a separate pull request that also carried two related fixes by another contributor.
Work I can contribute
Adversarial model testing, follow-up on unexpected behavior, source verification and clear evidence documentation. My accepted AI Safety Formalization Atlas contributions include source auditing and citation provenance. I am open to paid AI-evaluation, information-integrity and research-support roles and projects, including international remote work and relocation.
Training & participation
Lucky Break: Level Up (Medium Challenge)
Completed 6 of 6 scenarios. The training certificate records 4 of 5 models broken.
View training certificate and record →Additional participation: Breaking Ties
Participant certificate issued 12 October 2026, recording 3 of 5 scenarios and 3 of 5 models broken.
View participation certificate and full figures →Syntony Research — Trusted Red Team Network
Member of Syntony Research’s Trusted Red Team Network, a project-based network of independent specialists in adversarial AI evaluation.
Network membership; scope, responsibilities and compensation are agreed for individual engagements.
Claim provenance
Earlier testing record · 13 October 2026
Gray Swan Arena displayed 40 global unique breaks, 1,430 points and 415 submissions, with global rank #426. The September record had 31 unique breaks. Proving Ground separately displayed #81, top 5%, and 127 total breaks across chat, image, agent and indirect challenges. These are dated platform-reported results; rankings can change.
Evidence details and scope
The linked evidence pages preserve original captures, dates and structured transcriptions. Arena and Proving Ground metrics are separate, and platform counts do not independently reproduce every underlying result or establish general model failure rates. The Proving Ground area counts sum to 126 while the platform displays 127 total breaks; both values are retained. Active-challenge figures were provisional at capture time, and Lucky Break prizes are awarded by raffle. My Gray Swan testing is independent activity; Syntony membership and project engagements are distinct.
Dated Proving Ground record: rank #74, top 6%, on 29 July 2026.
The displayed total is 113; four visible area counters sum to 112. Arena figures are separate. This is not a current ranking or paid engagement.
Original evidenceDated Proving Ground record: rank #79, top 5%, with 127 platform-recorded total breaks on 30 September 2026.
Captured from the logged-out public profile. The displayed total is 127; visible area counters sum to 126. Arena separately shows rank #462, 31 unique breaks, 1,260 points and 354 submissions. This is dated platform evidence, not paid employment, security certification or independent reproduction of every result.
Original evidenceLucky Break: Level Up final result: 49th of 390 participants, with 15 platform-recorded breaks.
Final competition placing and platform-recorded breaks. Separate from the intermediate training certificate, global Arena totals and Proving Ground results. Platform counts do not independently reproduce every underlying result or establish a general failure rate. Competition prizes were awarded by raffle; no prize is claimed.
Original evidenceDated Arena record: 40 global unique breaks, 1,430 points and 415 submissions on 13 October 2026.
The public profile route was captured in the account holder's authenticated browser session. Arena showed rank #426, 40 unique breaks, 1,430 points and 415 submissions. Proving Ground separately showed #81, top 5%, and 127 total breaks. The active Lucky Break result is provisional and the event awards prizes by raffle. This record establishes platform-reported activity, not independent reproduction of every result or a prize award.
Original evidenceMember of Syntony Research’s Trusted Red Team Network since October 2026.
Nathan Heath’s public acknowledgement supports individual network membership. It does not establish Syntony employment or completed paid engagements; project participation, responsibilities and compensation are agreed separately.
Original evidenceGray Swan intermediate training completed: Lucky Break: Level Up (Medium Challenge), issued 14 October 2026; separate Breaking Ties participation certificate issued 12 October.
The training certificate records 6/6 scenarios and 4/5 models broken. The participation certificate records 3/5 scenarios, 3/5 models broken and rank 125/167. These are certificate-specific figures, separate from profile and leaderboard metrics; neither establishes a professional qualification or prize award.
Original evidenceContributed a merged fix to Basic Memory, an open-source knowledge base for AI assistants: its write tool no longer hands agents edit and delete calls to run unasked.
Acceptance covers this change and its regression test; it does not establish independent engineering proficiency.
Original evidenceSource review: 2026-11-11. This is a dated account; the linked sources may have changed.